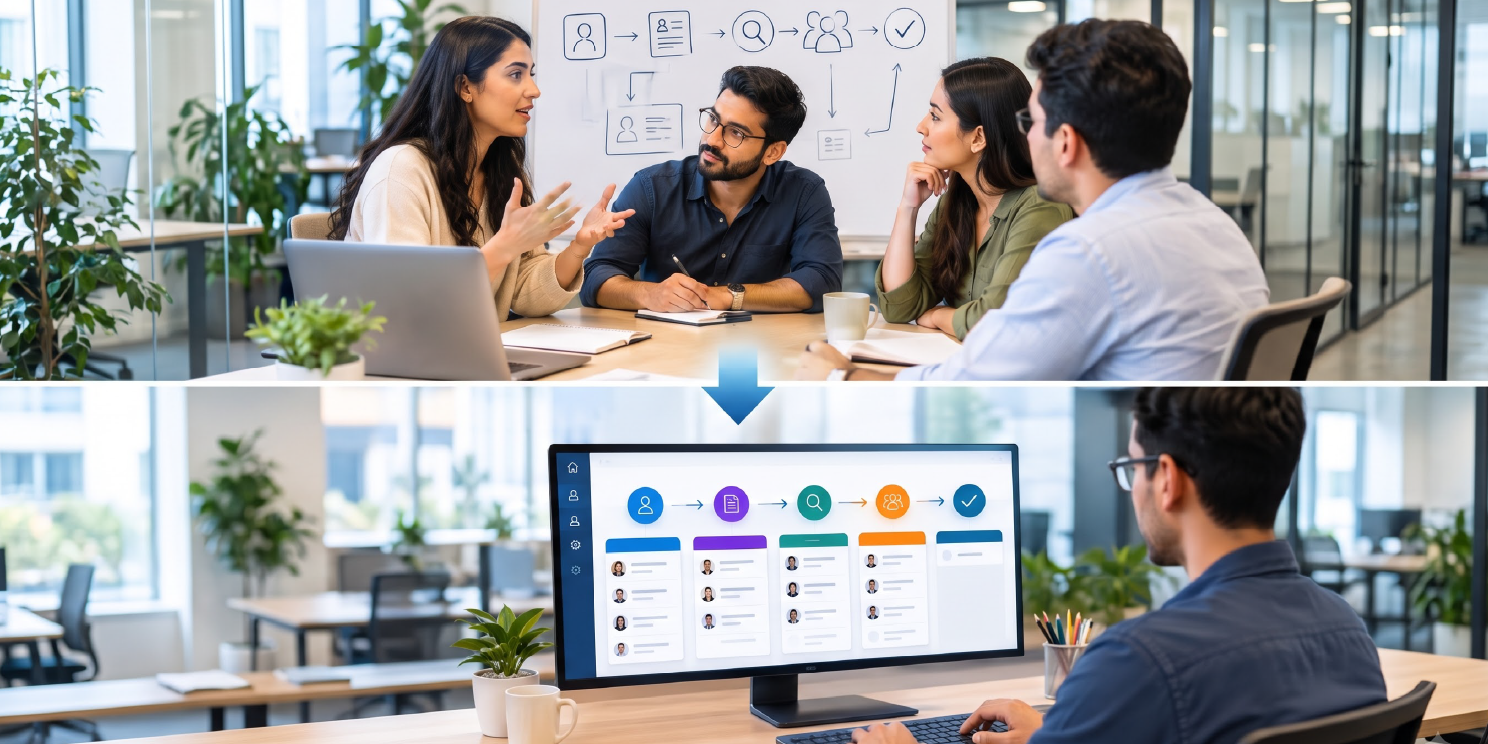
Nobody built a hiring workflow. They described one, and it got built for them.
- Category
- Mid-size tech employer, US
- Team
- Talent Acquisition, HR Operations
- Question
- Could the team screen a sudden spike in applications for a single role without hiring more recruiters or waiting weeks for an engineering team to build a custom tool?
- Time in TalkNAct
- Architecture running within the same day, full first batch of resumes scored by the next morning
- What changed
- A six-person recruiting team cleared a four-week backlog in under a week, without anyone on the team writing a workflow, picking a model, or filing a ticket with engineering.
The situation
A growing US software company posted a senior engineering role and got back more than 1,400 applications in ten days, roughly six times what the team had planned for. The recruiting team was six people, and the standard process had each recruiter manually screening resumes against the job description before passing shortlists to the hiring manager.
At the normal application volume, that process worked. At 1,400 applications, it didn't. Recruiters were already behind on the role's original timeline by the time the volume became clear. The team looked at two options. Hire temporary contract recruiters, which meant onboarding and training before anyone could actually start screening. Or build a scoring tool internally, which meant getting time on the engineering team's roadmap, a resource that had a backlog of its own and no reason to prioritize a one-off hiring project.
Neither option solved the actual problem, which was a deadline measured in days, not the weeks either option would take to stand up.
What they put in
The hiring manager described the objective directly, in plain language: review the incoming resumes against the job description and the must-have requirements, identify the candidates who best matched both the technical requirements and the stated experience level, and produce a ranked shortlist with the reasoning behind each score.
Nobody on the team specified which model to use, how to structure the evaluation, or what the underlying workflow should look like. That wasn't the team's job here. The brief was the input.
What TalkNAct built
From that brief, TalkNAct determined the agent architecture needed to deliver it: a requirement-understanding step that parsed the job description into concrete evaluation criteria, a resume-processing step that extracted structured information from documents that arrived in a mix of formats, an evaluation step that scored each candidate against the extracted criteria, and a recommendation step that produced a ranked shortlist with a stated rationale for each score.
The recruiting team never assembled that sequence themselves. They stated what they needed, and the architecture for this specific job got created around it. Different steps in the pipeline used different models, matched to what each step actually required, reasoning depth for the evaluation step, speed for the initial document parsing, rather than one model forced to handle every part of the job equally well.
What they asked, and what they changed mid-flight
Once the first batch of scores came back, the hiring manager reviewed a sample against candidates she already knew well from early resume screening, and flagged that the scoring was underweighting hands-on project experience relative to years of tenure. She said so conversationally, in the same thread: give more weight to project experience, less to raw years in the role.
TalkNAct adjusted the running approach without anyone redesigning the workflow or waiting for a new build. The next batch reflected the change. Later in the process, the team also asked to exclude a specific prior employer from influencing the score, since a cluster of recent hires from that company had turned out to be a poor fit for reasons unrelated to resume content. That exclusion went in the same way, as a conversational instruction rather than a rebuild.
What the workflow produced, and what it didn't decide
The shortlist came with reasoning, not just a number.
Every ranked candidate carried the stated basis for their score, so the recruiting team could see why someone ranked where they did and catch cases where the reasoning didn't hold up on a human read.
Human review stayed in the loop before any decision moved forward.
Recruiters reviewed the ranked list before anything was communicated to hiring managers or candidates. TalkNAct surfaced the recommendation. It did not make the final call on who got an interview.
The tool didn't replace judgment on close calls.
A handful of borderline candidates still went to a recruiter for a manual read, because the scoring system flagged the ambiguity itself rather than forcing a confident-looking number onto a case that didn't warrant one.
What changed
The four-week backlog the team had been facing cleared in under a week. The same six recruiters who couldn't keep pace with 1,400 resumes manually processed the full volume with the scoring workflow doing the first pass, and spent their own time on the shortlisted candidates and the ambiguous cases instead of reading every resume that came in.
- Before: Six recruiters, a 1,400-resume backlog, and a choice between slow contractor onboarding and an engineering build nobody had time to prioritize.
- After: A scoring architecture built the same day from a plain-language brief, adjusted twice in conversation as the team learned what good screening actually looked like for this role, with no new project, no new hire, and no engineering ticket.
More Case Studies
 TalkNAct
The dashboard they asked for turned into an alert system nobody had to build
A mid-sized US e-commerce retailer collected a steady stream of customer feedback: post-purchase ratings, support ticket transcripts, and open-ended comments left on product reviews. All of it fed...
Read full case study SegmentIQ
The age band was never the answer
A snack brand had a premium baked range ready for a regional pilot across grocery and convenience channels in six metro markets. The product team had a target: adults aged 25 to 34. It came from the...
Read full case study PersonaAI
The positioning line the room loved never got tested, and the brand was better off for it
A household cleaning brand was preparing its annual relaunch and had three candidate taglines on the table, all built around the idea of speed: "5-minute clean," "done before your coffee's ready,"...
Read full case study


Let's Talk AboutYour Next Insight.
Tell us what you are trying to decide and our team will show you how Insights Curry can help.